H_AI, the personal AI engine on my Mac Studio, has a good dashboard. But a dashboard is something you open. A friend is someone you text. Most of what I ask an assistant is small: a quick sum, a word I forgot, “read this to me”. For that, I don’t want a tab. I want a chat thread on my phone, next to my family and friends, that answers in a line or two.
I gave myself three rules. It had to be end-to-end encrypted. The chats had to live on my own hardware. And it had to work from anywhere, not only on the home Wi-Fi.
Why Matrix
My first thought was an open-source Slack, so I looked at Rocket.Chat. It ruled itself out on the one rule that mattered: in its encrypted rooms, bots can’t read the messages. A bot that can’t read is not much of an assistant.
Matrix works differently. Encryption happens on each device, and a bot is just another device in the room, with its own keys. It decrypts what I send, and encrypts what it replies. The server in the middle only ever stores ciphertext.
The Whole System
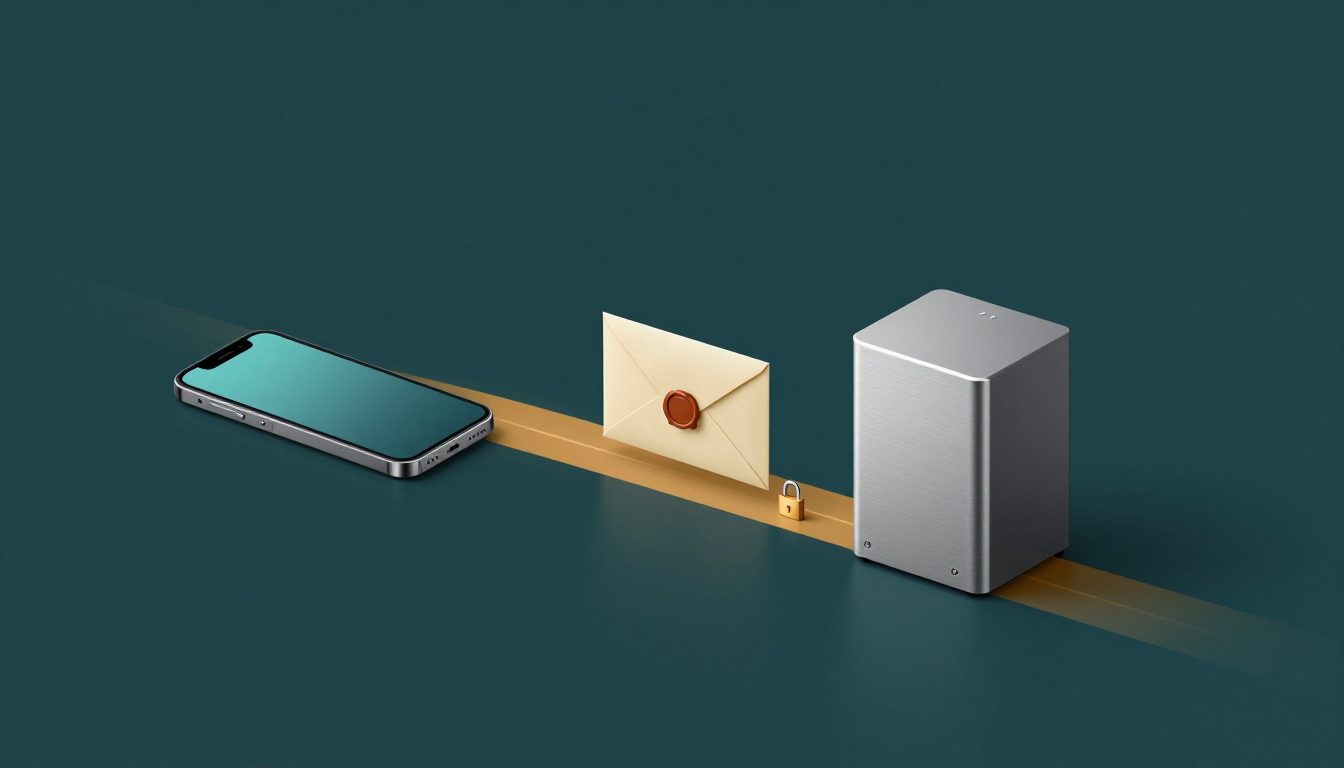
/claude ever leaves the house.One Message, Start to Finish
- 01I type on the phoneElement X encrypts the message before it leaves the device.
- 02It crosses TailscaleOnly devices signed into my own private network can reach the server at all. It is never published to the open internet.
- 03Synapse stores ciphertextThe server listens only on the Mac itself, and Tailscale hands it the traffic. It can’t read what it stores.
- 04hishambot decrypts and asks H_AIOver a pinned TLS connection, with one separate conversation per chat room.
- 05The answer streams backThe bot edits its own message as the words arrive, so it feels like someone typing, and every edit is encrypted again.
I also decided against using a public Matrix server for the account. My chats with my AI are exactly the kind of thing I don’t want on anyone else’s server, even encrypted. So everything stays on the Mac, and federation is switched off.
Failures That Looked Like Success, Again
In the AI engine article I wrote that failures there announce themselves as successes. This project kept proving it.
The bot answered, and I saw nothing. The logs said every reply was sent and encrypted. My phone showed an empty room. The reason: Element X hides messages from devices their owner hasn’t verified, and a bot has no second screen to tap “verify” on. The fix was a small script that does the cross-signing by hand, once, so the bot vouches for its own device the way a person would.
New rooms were silent. I created a chat, wrote to it, and waited. The bot had never been invited. Now a tiny module inside the server notices when I create a room and invites the bot into it a couple of seconds later.
Voice notes were two words long. I asked for a long text read aloud and got back a clip that said “voice equals Alloy”. The tool parser took only the first line of the request, which was the voice setting, and dropped the text under it. It also picked the wrong voice, because an old line in the system prompt still called Alloy the default.
Everything waited for the slowest thing. While an image or a recording was rendering, the bot answered nothing else. The Matrix library runs its handlers one at a time, so one slow job held up the whole chat. Now every message runs as its own background task. When I ask for a picture, I get “On it, keep chatting”, and I can ask what 2+2 is and get “4” while the image is still being drawn.
Making It Sound Like a Friend
The dashboard’s system prompt is written for long, careful answers. In a chat app, that reads like an essay in a text bubble. So the bot tells H_AI it is the messaging client, and H_AI adds a short persona for that request only: answer in a line or two, no headings, no preamble, no “great question!”.
I asked Claude to study the system prompts of OpenCode, an open-source coding agent known for being terse, and borrow what works: a few short example exchanges instead of long rules, hard line limits, and an explicit ban on openers and wrap-ups. Then I asked for one more thing: act like my Egyptian friend.
meezayak ya basha
hishambotTamam, el7amdulillah! How’s your day going?
me15% of 240?
hishambot36.
That took some tuning. The first version answered in full Franco, Arabic written in Latin letters, which is fun for a line and tiring for a paragraph. Now it speaks mainly English with at most a couple of Egyptian words, and switches to Egyptian Arabic only if I write in Arabic script. It is never rude to me; teasing is fine only when it is clearly warm. And when the news is sad or serious, the jokes stop completely.
The persona also kept losing to the much longer main prompt, so two things fixed it. A one-line reminder now rides on my latest message only (it is never saved in the history), and I asked Claude to cut the persona from about 940 tokens to 450. Shorter worked better.
Fast Enough to Feel Like Texting
A friend who takes a minute to reply to “hi” isn’t much of a friend. The bot uses Qwen 3.6 35B-A3B, a mixture-of-experts model that ran about 96 tokens per second on the Mac, against about 21 for the larger Qwen 3.8 I use on the dashboard. For a two-line answer, that is the difference between instant and waiting.
Every chat room is its own conversation. A new room starts with no memory of the others, and !new starts a fresh thread in the same room. The dashboard’s own conversation is never touched.
Power Mode
Sometimes the local model isn’t enough. Starting a message with /claude sends just that one message to Claude instead, through the same server, in the same thread. !power on keeps a whole room on Claude until I turn it off. Local stays the default, and the cloud is something I choose.
A Voice That Sounds Like Me
When I ask for something read aloud, the bot answers with a voice note in my own cloned voice. Before it’s spoken, the text goes through the same humanize step as my bedtime stories: the Markdown comes out, lists become sentences, “%” becomes “percent”, and the fast model adds a few delivery cues like warmly for the voice to perform.
I noticed the voice changed a little from one clip to the next. The voice model clones afresh on every render, so each clip sounded like a slightly different me. A fixed seed solved it. I checked the result with a transcription model too: none of the cues were read out as words.
Running It Without Thinking About It
Everything starts by itself when the Mac logs in. A small light in the menu bar turns green, yellow or red, and shows each piece on its own (the AI engine, Matrix, the bot, Tailscale, the models, search and voice) with start and stop buttons. Voice used to be the one thing that was always down, because nothing ever started it. Now it starts with the AI engine.
Keeping It Private
Being private was the whole point, so I treated it as a feature to test, not a hope:
Nothing public. Only my own devices can reach the server, through Tailscale. No sign-ups, no federation, and it is never exposed to the open internet.
No secrets in the code. Passwords and keys stay in local files that git ignores. I had Claude check every file and the whole git history for them. It found none, but it did find a rotated log file that had slipped into a commit. There were no passwords in it, only device addresses, and it came out of the history before anything was shared.
No passwords on the command line. A security review flagged that my password-change script passed the password as an argument, which any program on the Mac can see. It now uses a hidden prompt instead.
Approvals that can’t be mixed up. Once the bot could do several things at once, a plain “yes” could have approved the wrong action. Now it only approves the one waiting request, or the one I reply to.
What’s Next
Sending voice notes to the bot, not only getting them back. Sending it a photo and asking about it. A short morning brief that arrives by itself. And the usual work: finding the places where it fails quietly, and making them speak up.
The server, the bot and this article were built with Claude Code.